Precision Data Mapping for Audit Readiness
By Formiti Global DPO Team, Formiti Data International
A practical guide to mapping personal data flows, validating changes and maintaining processing records that support privacy assessments and audit evidence.
Topics: Data Mapping, ROPA, GDPR, Privacy Operations
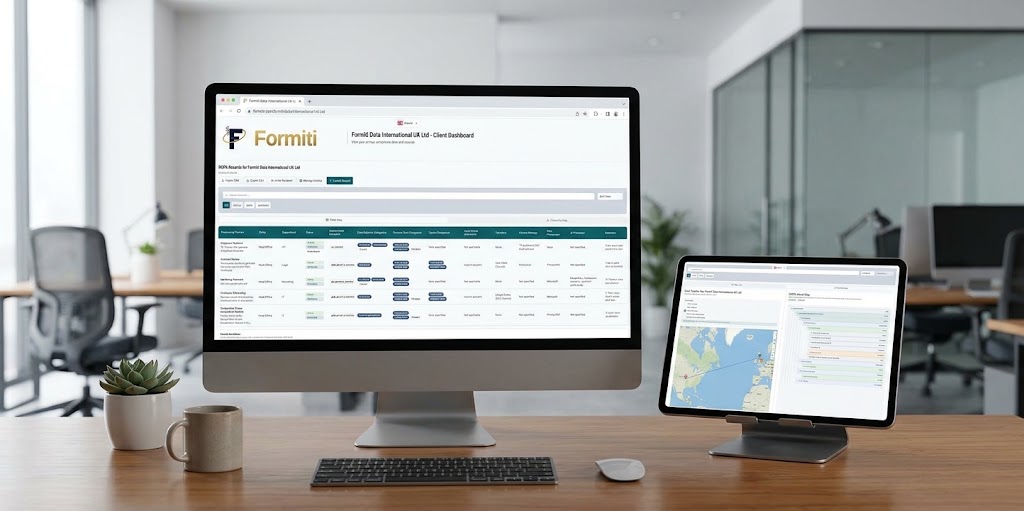
Putting this into practice? See how Privacy360's ROPA software handles it. Keep an Article 30 record of processing with owners, data maps and processor links.
The Blueprint of Integrity: Defining Data Mapping in Modern Governance
What happens when the same customer exists as three different records in three different systems, and no one can say which one the regulator will ask about? That question is what data mapping answers. It's the bridge between disparate source models and a unified target architecture — a way to reconcile systems that represent the same business facts differently.
Effective mapping operates on three levels:
- Physical field mapping — reconciling column names, data types, encodings, and constraints between a source system and its destination.
- Logical business rule mapping — encoding how meaning transfers, including derivations, conditional logic, and lawful-basis tagging, ensuring compliance with legal standards.
- Framework alignment — binding every documented flow to a regulatory obligation under the GDPR, sectoral rules, and applicable AI governance requirements.
Documented ownership, checks and review make a map more useful as compliance evidence.
Foundational Concepts: What Does Data Mapping Mean in Practice?
Data mapping means specifying, field by field, how information moves and changes shape between systems. The artifact is a source to target mapping document (STTM): source field, target field, data type, transformation rule, validation test, owner. Engineering teams treat it as the source of truth; auditors treat it as evidence.
The 2026 Operational Framework for Data Integration and Migration
High-stakes migrations follow a Source-Transform-Validate lifecycle. Source means discovery and profiling before any rule is written. Transform applies the documented logic, with each rule versioned. Validate proves, through reconciliation counts and sampled record comparison, that meaning survived the journey.
Classification tools can help identify personal data across structured and unstructured sources, but teams should check the results before relying on them.
Embedded review sits on top. AI proposes mapping logic and flags anomalies; a qualified human accepts, rejects, or amends, and the decision is logged.
Step-by-Step Execution: Can You Provide an Example of Data Mapping?
Consider a legacy CRM field, Customer_Name, holding "SMITH, JOHN A." as a single string. The target is a structured JSON-LD Person object with givenName, familyName, and additionalName. The mapping rule must parse on the delimiter, normalise casing, strip trailing punctuation, and handle records where no comma exists.
Data cleansing is crucial in this phase: null handling, duplicate collapse, and rejection routing for records that fail parsing. Data mapping in Excel remains a reasonable entry point — a shared spreadsheet template gets legal, engineering, and business owners agreeing on definitions before anyone writes transformation code.
Reviewing the map as processing changes
Once flows are documented, compare them with actual processing activities. Check whether new recipients, changed retention periods or transfers need an update to the processing record and any linked assessment. Record who reviewed the change and when.
Building the Capability: What Tool is Used for Data Mapping?
Spreadsheets are often the starting point for programmes, but they can also be where progress stalls. They capture intent well and enforce nothing. ETL mapping platforms and iPaaS services move the logic into executable, testable pipelines with lineage metadata attached, which is the difference between a description of a data flow and a governed one.
Internal tooling teams frequently build their own interfaces — reusable front-end components that let business users match source columns to target schemas without touching SQL mapping. Cloud-native connectors handle real-time synchronisation where batch windows no longer fit.
A connected privacy platform can bring mapping, assessments and vendor review together around shared records.
The Data Mapping Skill Set: What Skills Are Needed for Success?
Technically, practitioners need working SQL, fluency in XML mapping and JSON schema structures, and enough API literacy to read pagination, authentication, and rate-limit behaviour. Schema mapping across relational, document, and event-stream models is now baseline rather than specialist.
Technical skill alone produces elegant maps that are legally wrong. Domain expertise ensures transformation rules match statutory definitions — what counts as consent, what constitutes a joint controller relationship. Privacy-first engineering completes the set: minimise, mask, and restrict access to personal data during the mapping work itself.
Governance Alignment: Mapping for Global Privacy and AI Compliance
Data mapping can support the records of processing activities required under GDPR Article 30. Purposes, categories, recipients, retention periods, and transfer mechanisms all originate from the same documented flows, which is why the ROPA module can use mapping output without duplicating the work.
AI governance raises the bar. Where AI is involved, document the data sources and processing purposes relevant to each system in an AI System Register, alongside the risk classification and evidence appropriate to its use. Operationalised compliance means the map is a living record with change history, not a PDF dated last year.
Limitations and Considerations: Where Traditional Mapping Fails
A common failure is the 'stale map trap'. A discovery exercise completed in March describes an estate that no longer exists by June, because a schema changed, a vendor was onboarded, and a new analytics pipeline shipped. Static documentation becomes a liability the moment a regulator relies on it.
Unstructured content defeats field-to-field logic entirely. Contracts in PDF, support call recordings, and images carry personal data that no column header announces, and classification confidence there is materially lower than in a relational database map.
A genuine trade-off exists between automated discovery and manual validation: automation covers breadth quickly, human review earns defensibility slowly. Enterprise-wide discovery is expensive and slow, and programmes that pretend otherwise usually under-scope validation first.
Common Failure Modes and Fixes
Schema mismatch. A source field stores an identifier as a string with leading zeros; the target expects an integer. Silent coercion destroys data. Fix this with explicit type declarations and rejection handling rather than default casting.
Loss of context. A technical map showing tbl_usr.dob → subscriber.birth_date says nothing about lawful basis, retention clock, or residency constraint — and that absence is what produces regulatory misinterpretation.
The fix for both is a metadata management layer travelling with every map: ownership, purpose, sensitivity classification, jurisdiction, and version.
Future Implications: The Shift Toward Autonomous Data Lineage
Self-healing maps are the near-term direction. When a database mapping layer detects a new column or a changed constraint, it should propose the downstream mapping update, flag affected assessments, and queue human confirmation — rather than waiting for an annual review to discover the drift.
That points toward Lineage-as-Code: mapping definitions held in version control, validated in the CI/CD pipeline, and blocked from merge when a schema change breaks a documented flow or orphans a retention rule. Governance shifts to a build-time check rather than a post-hoc audit.
Decentralised identity will stretch the model further, as attributes increasingly sit in user-controlled stores and maps must describe access rights rather than stored copies. The aim is to keep changes traceable and the documentation useful to the teams responsible for it.
Where to Look Next
Consult primary sources alongside your own policies. Manufacturer documentation for your specific ETL, catalogue, and governance platforms defines actual transformation and lineage behaviour. ISO/IEC standards bodies publish the data interchange and metadata protocols your schemas should conform to. Sector regulators and national data protection authorities publish residency and record-keeping expectations that vary by jurisdiction — and for multi-entity groups, regional data residency options may also matter.
Key Takeaways: The Bottom Line on Data Mapping
Data mapping is essential for every integration, migration, and compliance initiative — nothing downstream is trustworthy without it. Doing it well requires technical schema and SQL fluency, along with genuine regulatory domain knowledge. ML-assisted discovery can help at enterprise scale, but it still needs human validation; and an audit-ready posture means retiring static spreadsheets for operationalised, versioned workflows.
Book a demo to see how Privacy360 connects processing records, assessments and governance across entities.