The Evolution of PII Data Protection in 2026
By Formiti Global DPO Team, Formiti Data International
How PII is defined and classified in 2026, where exposure risk is highest, and why operationalised governance beats fragmented spreadsheets under scrutiny.
Topics: PII, Data Protection, Compliance, AI Governance, Risk
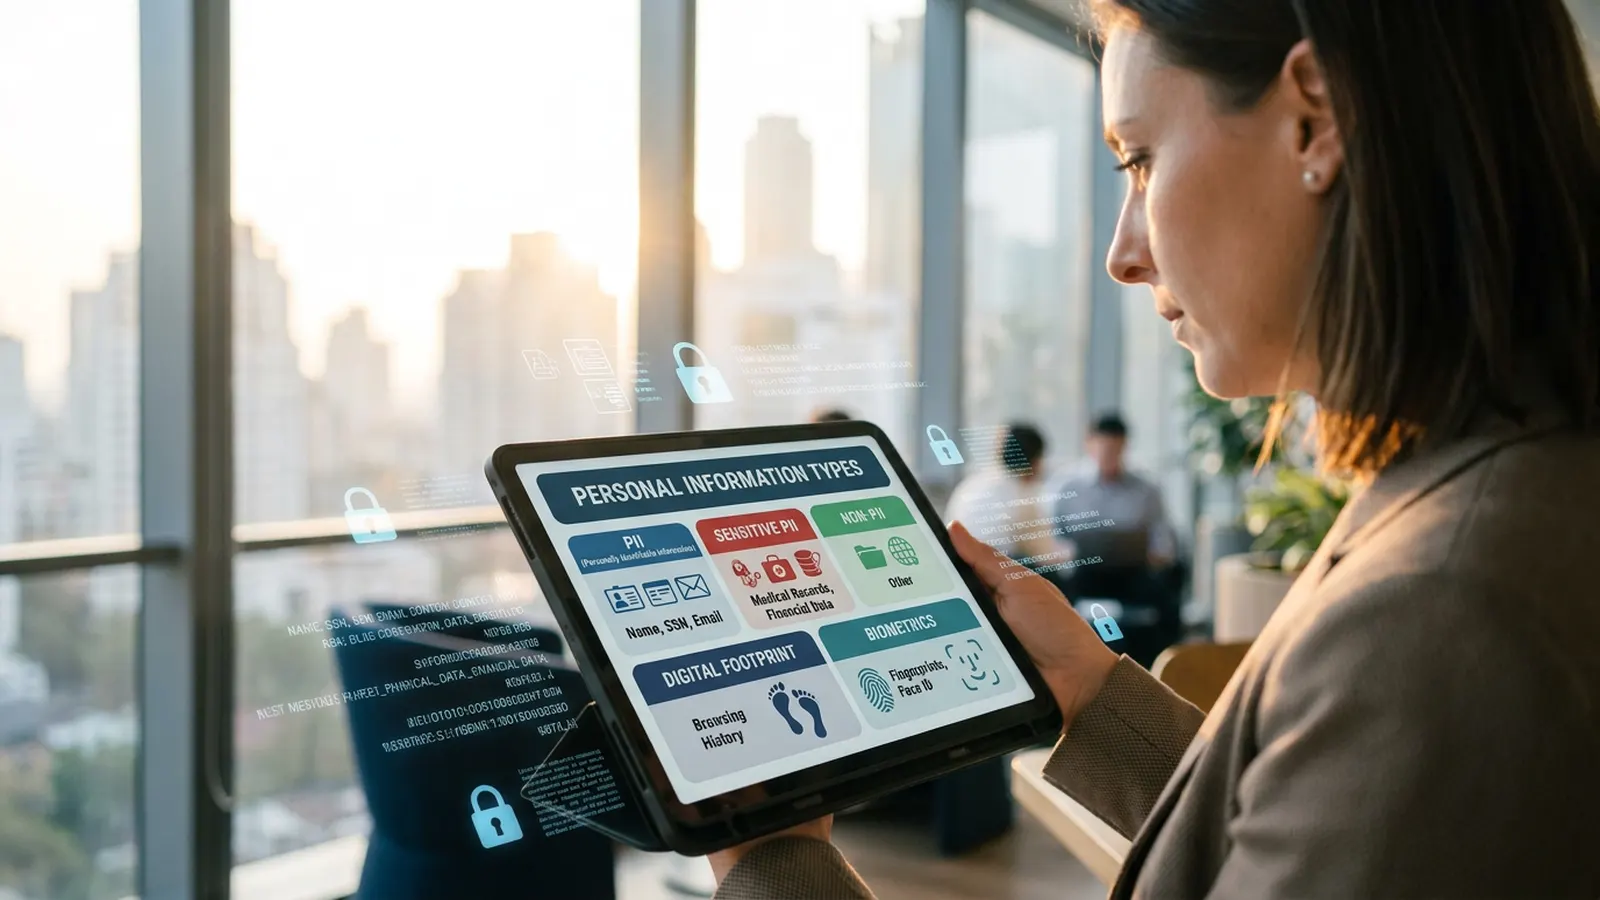
Personally identifiable information is no longer a static checklist of obvious fields like names and Social Security numbers. In 2026, it is a dynamic, jurisdiction-sensitive category that expands with every new data source, AI system, and cross-border transfer your organisation touches.
This guide is written for privacy and compliance professionals managing that complexity at scale — in-house teams juggling multi-jurisdictional obligations, legal entities operating across the EU, US, and APAC, and product and security owners building systems that process personal data by design.
What follows is a structured walkthrough of how PII is defined and classified today, where exposure risk is highest, and how operationalised governance — not fragmented spreadsheets — is the only approach that holds up under regulatory scrutiny. You will also find a direct look at how AI systems are reshaping the compliance perimeter and what audit-ready workflows need to account for in response.
The New Reality of Personally Identifiable Information (PII)
Imagine a procurement team exporting a "harmless" spreadsheet of supplier contacts — names, office zip codes, a column of internal reference numbers. Six months later, that file surfaces in an incident review as the pivot point for a credential-stuffing campaign. Nothing in it looked sensitive on its own.
This illustrates the core of what is PII in 2026: an individual's digital fingerprint, assembled from fragments. The NIST-style definition of PII data centres on information that can distinguish, locate, or trace a person's identity, either alone or combined with other linked or linkable data. European and APAC regimes go broader, treating almost any identifiable signal as personal data.
- Linked information — directly tied to a named person
- Linkable information — innocuous alone, identifying when joined to another dataset
- Jurisdictional drift — the same field classified differently across regions
Isolated data points are rarely safe. Spreadsheets alone can't track these complexities.
Classification Framework: Sensitive vs. Non-Sensitive PII
The definition of PII data is the starting point for any classification decision: information that can distinguish, locate, or trace a person's identity, either directly or when combined with other linked or linkable data. From that baseline, two tiers emerge with meaningfully different control obligations.
Sensitive PII — Social Security numbers, biometric templates, health records, financial account details — demands encryption, strict access controls, and a documented lawful basis before any processing begins. Non-sensitive PII covers publicly available attributes like zip code, employer, or general demographic fields, which carry lower individual risk in isolation.
The contextual shift matters more than the label, though. Aggregate zip code, birth date, and gender and you approach unique identification. Intent and combination, not the field name, determine the control tier you owe that record — which is why static category lists fail teams managing data at scale. Classification has to account for how data moves and joins, not just what it looks like at rest.
5 Critical Examples of PII Data to Monitor
The PII data definition — information that can distinguish, locate, or trace a person's identity, either directly or in combination with other linked or linkable data — determines which fields your monitoring programme must cover. Useful PII data examples cluster into five categories, each carrying distinct control obligations:
- Direct identifiers — full names, passport and DoD ID numbers, home addresses
- Digital identifiers — IP addresses, device IDs, persistent cookies
- Biometric assets — facial recognition patterns and fingerprint metadata in enterprise authentication
- Financial markers — payment card numbers and linked bank routing details
- Medical records — Protected Health Information as a subset of sensitive PII
Each category needs its own retention rule, access tier, and processing record. Treating them as a single undifferentiated block is where most programmes introduce untracked exposure.
The High Stakes of Data Exposure and Identity Theft
For cross-border legal entities, a PII breach isn't one event — it's parallel notification clocks, parallel regulators, and parallel evidence demands. A single incident in a shared CRM can trigger obligations in the EU, the US, and APAC simultaneously, each with distinct timelines and each expecting documentation you either have or don't.
The dominant threat vectors stay consistent: social engineering against privileged staff, credential stuffing using previously leaked identifiers, and insecure or undocumented API endpoints quietly exposing records that never appeared in a data map.
For individuals, the damage has a long tail. Static identifiers — national ID numbers, biometric templates — can't be reissued the way a password can. Fraud built on them resurfaces years later.
Regulators have raised the floor accordingly. GDPR enforcement, evolving US state privacy laws, and the EU AI Act converge on the same expectation: demonstrable governance. Penalties follow the absence of evidence as much as the breach itself, which is why audit-ready records beat retrospective reconstruction.
Why the DoD ID is Considered PII (Even if it Appears Public)
A common misconception holds that identifiers printed on badges or shared routinely across systems lose their personal character. They don't. Ubiquity doesn't equate to anonymity — and the DoD ID is a clear illustration of why.
Among the most instructive PII data examples in the government and defence sector, the DoD ID number demonstrates how a static, government-issued identifier functions as a precision correlation key. It persists across employers, vendors, clearance reviews, and decades, enabling disparate datasets to be joined with a reliability that makes it operationally indistinguishable from a Social Security number in terms of re-identification risk. Combine it with a name, a duty station, or a benefits record — all fields that appear in routine administrative exports — and you have a profile that satisfies any working definition of PII data.
Security through obscurity fails here because the identifier was never secret. Its risk comes from permanence and cross-system linkability, not confidentiality. That's the same logic that makes device IDs, persistent cookies, and biometric templates high-priority fields in any classification framework: the danger isn't visibility, it's the ability to anchor an identity across time and context.
What is Not Considered PII: Understanding Anonymisation
Understanding what falls outside the PII boundary requires more precision than most programmes apply. De-identified data has direct identifiers removed — names, account numbers, contact details — but it remains re-identifiable with effort, which means it doesn't clear the legal threshold for true anonymisation under GDPR or equivalent regimes. Truly anonymous data must meet a higher standard: re-identification must be reasonably impossible, accounting for available auxiliary datasets, compute power, and the realistic capabilities of a determined adversary.
The gap between those two states is where most exposure hides. Triangulation defeats weak de-identification routinely. Three quasi-identifiers — zip code, date of birth, and gender are the canonical PII examples — often suffice to single out an individual in a dataset that appeared safely stripped. Fields that look non-identifying in isolation become identifying in combination, which is the same logic that makes linkable PII examples like device IDs and behavioural signals high-priority classification targets even when no name is attached.
Business contact information sits in a separate tier under some regimes, with lighter obligations attached. That carve-out is real but narrower than most teams assume — it's jurisdictional, it doesn't extend to personal email addresses or home locations, and it doesn't survive re-combination with other records. Treating it as a blanket exemption is a common source of untracked exposure in vendor and procurement workflows.
Operationalising Protection: From Fragmentation to Command Centres
Most privacy programmes fail on operations, not intent. Records of processing live in one spreadsheet, vendor assessments in another, DSAR logs in a shared inbox, and the AI inventory nowhere at all. When a regulator asks a question, the answer is assembled under pressure from sources nobody trusts.
The problem compounds when you consider the range of examples of PII that modern programmes must track: direct identifiers like full names and Social Security numbers, digital signals like IP addresses and device IDs, biometric templates, financial account details, and health records — each with its own retention rule, access tier, and jurisdictional handling requirement.
Fragmented tooling cannot hold that complexity. Spreadsheets do not trigger downstream assessments when a new processing activity touches sensitive fields, and shared inboxes do not produce audit trails regulators will accept. An audit-ready command centre replaces that fragmentation. Privacy360's ROPA module centralises records of processing with audit trails, downstream assessment triggers, and regional jurisdiction handling, so the data map stays current by design rather than by annual scramble.
Embedded AI-assisted review does the work humans cannot sustain: surfacing personal data buried in unstructured Excel files, PDFs, and contract attachments that keyword scanning misses. Privacy-first engineering pushes the same discipline upstream — classification decisions made during product design, not retrofitted after launch. Automated discovery keeps the inventory honest between reviews, ensuring that newly identified PII categories are captured as they emerge rather than discovered during an incident.
The Role of Hashing and Encryption in Data Privacy
Hashing alone rarely anonymises. Unsalted hashes of predictable values — email addresses, phone numbers — fall to rainbow tables immediately. A per-record salt plus a secret pepper, with a deliberately slow algorithm, raises the bar meaningfully.
Encryption at rest protects stored volumes, in transit protects movement, and in use protects live processing. Legacy masking that simply obscures characters offers little resistance in a high-compute environment.
Blocking 100% of Risky Data Exports
Blocking every risky Excel or CSV export is technically possible but operationally destructive. Strict egress filtering stalls legitimate finance, HR, and analytics work within days, and users route around it.
Policy-based blocking works better: tier controls by data classification, allow approved workflows with logging, and require justification only at the sensitive tier. Common DLP failure modes include over-broad pattern matching, blind spots in encrypted archives, and alert volumes nobody triages.
Future Implications: PII Governance in the Age of Generative AI
Generative AI doesn't just process PII — it absorbs it in ways that resist the standard remediation playbook. Prompts containing customer records, fine-tuning sets built from production exports, and retrieval indexes pointing at unfiltered document stores all create exposure that no deletion request cleanly resolves. Erasure rights and model weights are an uncomfortable fit, and that tension isn't going away.
The PII data definition — information that can distinguish, locate, or trace a person's identity, either directly or in combination with other linked or linkable data — applies with full force inside AI pipelines. A model trained on support tickets, HR records, or contract attachments has ingested PII whether or not anyone mapped it as a processing activity.
That mapping gap is where regulatory exposure accumulates. The workable framework treats AI systems as processing activities, not experiments. Register every system, classify its risk under the EU AI Act, document the data it consumes, and assess it with the same rigour applied to a vendor or a new product feature. Privacy360's AI System Register does this alongside existing DPIA and LIA workflows rather than in a parallel stack — the distinction between a register and a simple inventory is what makes it defensible under scrutiny.
Reactive patching after a model ships isn't a viable strategy anymore. Expect synthetic data to displace real personal data in testing and development environments, removing an entire category of exposure from lower-tier systems.
For higher-risk deployments, the EU AI Act's conformity requirements will push AI governance into the same audit-ready workflows that GDPR compliance already demands — which means organisations that have already operationalised their privacy programme are better positioned than those still managing it through spreadsheets.
Common Misconceptions and Limitations
Encryption is a control measure, not compliance itself. It says nothing about lawful basis, retention, transfer mechanisms, or subject rights — the areas regulators actually examine.
Zero Trust suits dynamic access patterns but adds friction with little benefit for genuinely public, low-risk datasets. Apply it where sensitivity justifies it.
Automated discovery also underperforms in specialised industries where identifiers are proprietary, non-standard, or encoded — human review remains necessary.
How to Find Credible Sources for Compliance Standards
Start with primary texts, not summaries. Regulation and guidance from supervisory authorities carry the definitions enforcement actually uses — including how specific PII data examples like biometric templates, device identifiers, and health records are classified across jurisdictions. Secondary commentary lags amendments and rarely reflects how regulators apply definitions in practice. Consult vendor and manufacturer documentation for storage locations, retention defaults, and sub-processor chains.
Procurement questionnaires often surface what marketing pages omit — including which PII data examples a given system processes, where it stores them, and whether sub-processors handle sensitive categories like financial account details or medical records. Sector bodies in healthcare, financial services, and telecoms publish benchmarks that translate broad statutory language into testable controls.
These are particularly useful for mapping jurisdiction-specific treatment of PII data examples that sit in contested territory — behavioural signals, persistent cookies, and quasi-identifiers that become identifying in combination.
Summary: What You Need to Know About PII
Personally identifiable information covers any data that can trace an identity, including digital metadata most teams still treat as technical exhaust. The PII data definition you operate under should be the broadest one applicable across your jurisdictions, not the most convenient.
Sensitive categories demand stronger encryption and tighter access control. Non-sensitive fields become sensitive through aggregation. Multi-jurisdictional risk is manageable only when compliance is operationalised in one audit-ready system, and AI governance now sits inside that system rather than beside it. For a worked set of field-level examples, see our companion PII data examples and classification guide.
Frequently Asked Questions About PII Data
Is an IP address considered PII? Generally yes. Most current regimes treat it as an identifier because it links to a person when combined with logs or account data.
Can anonymised data be reversed? Weakly de-identified data often can, through triangulation with external datasets. True anonymisation must resist that.
What's the first step to securing PII? Identify and map it. Browse the Privacy360 modules or book a demo to see how discovery, ROPA, and assessments connect.
Common questions
- Is an IP address considered PII?
- Generally yes. Most current regimes treat it as an identifier because it links to a person when combined with logs or account data.
- Can anonymised data be reversed?
- Weakly de-identified data often can, through triangulation with external datasets. True anonymisation must resist that.
- What is the first step to securing PII?
- Identify and map it. A documented inventory of where personal data lives, who can access it and how it is classified is the foundation every other control depends on.